
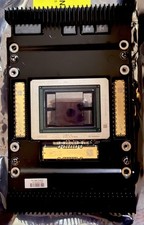
AMD Instinct MI100 OAM module
Live eBay prices, cheapest first. The best one right now is $720.00 (used).
Not a PCIe card. An undocumented MI100 server module from an OEM system (AMD only sold the MI100 as a PCIe card). No known server or OAM-to-PCIe adapter runs it, and it needs a 48 V supply. The chip is the PCIe MI100's (ROCm supports it), so for a workstation the PCIe MI100 is the same GPU that works. The PCIe version: AMD Instinct MI100, from $1,240 →
Specs
- VRAM
- 32 GB HBM2
- Bandwidth
- 1,229 GB/s
- FP32
- 23.1 TFLOPS
- FP16
- 185 TFLOPS
- Power
- 300 W
- Connector
- OAM (PCIe 4.0)
- Released
- 2020
- Llama 3.1 8B at Q4 (est.)
- 89–152 tokens/s
Price right now
Live on eBayFrom the live listings below; shipping included.
Listings
Live on eBay| Listing | Condition | Price | Checked |
|---|---|---|---|
| Used | $720.00or best offerfree shipping |
Auctions ending soon
No auctions ending soon right now.
Prices include shipping and were read from eBay at the time shown. They can change: check the listing before you buy.
Owner reviews
No owner reviews yet. Own one? Tell others how it runs.
From signed-in owners, checked before they're published. PerGB doesn't pay for or edit reviews.
How it compares
Live on eBay- Software: ROCm (on AMD's support list).
Faster, for the least
- NVIDIA A100 SXM4 40 GB: $2,195, 270% of the GeForce RTX 3090, 40 GB
- AMD Instinct MI250: $4,995, 422% of the GeForce RTX 3090, 128 GB
- NVIDIA GeForce RTX 5090: $5,000, 237% of the GeForce RTX 3090, 32 GB
From the live listings of every GPU, shipping included; performance against the GeForce RTX 3090 (FP16 or FP32 compute and memory bandwidth). Updated with every build.
Local AI: what it runs
| Model (Q4, 8K context) | Instinct MI100 OAM module needed | Costs now | Speed (est.) |
|---|---|---|---|
| Llama 3.1 8B | 1 card | $720.00 | 89–152 tokens/s |
| Qwen3 14B | 1 card | $720.00 | 48–82 tokens/s |
| gpt-oss 20B | 1 card | $720.00 | 118–203 tokens/s |
| Gemma 3 27B | 1 card | $720.00 | 26–44 tokens/s |
| Qwen3 32B | 1 card | $720.00 | 22–37 tokens/s |
| Llama 3.3 70B | 2 cards | not enough listings | 10–17 tokens/s |
| gpt-oss 120B | 3 cards | not enough listings | 83–143 tokens/s |
| Qwen3 235B-A22B | 5 cards | not enough listings | 19–33 tokens/s |
| DeepSeek R1 / V3 671B | more than 8 | — | — |
Cost: that many of the cheapest live listings. Speed: an estimate from the memory bandwidth for one person chatting. Try other models, sizes and contexts.
Decision models
| Model (Q4, 8K context) | Instinct MI100 OAM module needed | Costs now | Per question (est.) |
|---|---|---|---|
| Julia-10.144B | 1 card | $720.00 | 5.5–12 ms |
| Laya0.421B | 1 card | $720.00 | 9.1–20 ms |
| Kev-4B4B | 1 card | $720.00 | 22–47 ms |
| lev4B | 1 card | $720.00 | 66–141 ms |
| OpenJev27B | 1 card | $720.00 | 79–168 ms |
| Clef27B | 1 card | $720.00 | 79–168 ms |
| Perplexity Decider v1.227B | 1 card | $720.00 | 79–168 ms |
| mammoth-127B | 1 card | $720.00 | 79–168 ms |
Decision models score the options you give them instead of writing text, so they're timed per question. The time is scaled from each model's reported speed on an RTX PRO 6000 by this card's compute and memory bandwidth, within about half either way. About the models.
Compare elsewhere
Search other shops for AMD Instinct MI100 OAM module. These open the shop's own search; we don't show their prices here.