
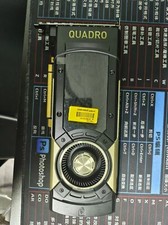
NVIDIA Quadro GV100
Live eBay prices, cheapest first. The best one right now is $1,500 (used).
Specs
- VRAM
- 32 GB HBM2
- Bandwidth
- 870 GB/s
- FP32
- 16.7 TFLOPS
- FP16
- 118 TFLOPS
- Power
- 250 W
- Connector
- PCIe 3.0
- Released
- 2018
- Launch price
- $8,999
- CUDA compute
- 7.0
- Llama 3.1 8B at Q4 (est.)
- 90–135 tokens/s
Volta: no longer supported by CUDA 13; CUDA 12 builds of PyTorch, vLLM and llama.cpp still run it.
Price right now
Live on eBayFrom the live listings below; shipping included.
Listings
Live on eBay| Listing | Condition | Price | Checked |
|---|---|---|---|
| Used | $1,500or best offer−27%shipping not listed | ||
| Used | $1,505−27%+$5.00 shipping | ||
| Used | $1,588or best offer−23%free shipping | ||
| Used | $1,705or best offer−17%free shipping | ||
| Open box | $1,705−17%+$5.00 shipping | ||
| Used | $1,800or best offer−12%free shipping | ||
| Used | $2,039or best offerfree shipping | ||
| Used | $2,050or best offerfree shipping | ||
| Used | $2,050or best offerfree shipping | ||
| Used | $2,050or best offerfree shipping | ||
| Used | $2,052or best offerfree shipping | ||
| Used | $2,052or best offerfree shipping | ||
| Used | $2,055or best offerfree shipping | ||
| Used | $2,055or best offerfree shipping | ||
| Used | $2,055or best offerfree shipping | ||
| New | $2,135or best offer+$35.00 shipping | ||
| Used | $2,155or best offerfree shipping | ||
| Used | $2,530or best offerfree shipping | ||
| Used | $2,530or best offerfree shipping | ||
| Used | $2,835or best offerfree shipping | ||
| Open box | $2,880or best offerfree shipping | ||
| Used | $2,956or best offer+$38.88 shipping | ||
| Used | $3,495free shipping |








Auctions ending soon
No auctions ending soon right now.
Prices include shipping and were read from eBay at the time shown. They can change: check the listing before you buy.
Owner reviews
No owner reviews yet. Own one? Tell others how it runs.
From signed-in owners, checked before they're published. PerGB doesn't pay for or edit reviews.
How it compares
Live on eBay- #5 of 33 PCIe GPUs with 32 GB or more for the money: $1,207 per GeForce RTX 3090 of performance.
- Software: CUDA 9.0 to 12.9 (not CUDA 13).
As much VRAM, about as fast, for less
- NVIDIA Tesla V100 PCIe 32 GB: $975.00, 123% of the GeForce RTX 3090, 32 GB
- NVIDIA Tesla V100S PCIe: $1,099, 149% of the GeForce RTX 3090, 32 GB
- AMD Instinct MI100: $1,240, 185% of the GeForce RTX 3090, 32 GB
Faster, for the least
- NVIDIA GeForce RTX 4090: $2,094, 158% of the GeForce RTX 3090, 24 GB
- NVIDIA A30: $2,459, 152% of the GeForce RTX 3090, 24 GB
- NVIDIA GeForce RTX 4090 D 24 GB: $3,097, 149% of the GeForce RTX 3090, 24 GB
From the live listings of every GPU, shipping included; performance against the GeForce RTX 3090 (FP16 or FP32 compute and memory bandwidth). Updated with every build.
Local AI: what it runs
| Model (Q4, 8K context) | Quadro GV100 needed | Costs now | Speed (est.) |
|---|---|---|---|
| Llama 3.1 8B | 1 card | $1,500 | 90–135 tokens/s |
| Qwen3 14B | 1 card | $1,500 | 48–73 tokens/s |
| gpt-oss 20B | 1 card | $1,500 | 120–179 tokens/s |
| Gemma 3 27B | 1 card | $1,500 | 26–39 tokens/s |
| Qwen3 32B | 1 card | $1,500 | 22–33 tokens/s |
| Llama 3.3 70B | 2 cards | $3,005 | 10–15 tokens/s |
| gpt-oss 120B | 3 cards | $4,593 | 84–127 tokens/s |
| Qwen3 235B-A22B | 5 cards | $8,003 | 20–29 tokens/s |
| DeepSeek R1 / V3 671B | more than 8 | — | — |
Cost: that many of the cheapest live listings. Speed: an estimate from the memory bandwidth for one person chatting. Try other models, sizes and contexts.
Decision models
| Model (Q4, 8K context) | Quadro GV100 needed | Costs now | Per question (est.) |
|---|---|---|---|
| Julia-10.144B | 1 card | $1,500 | 6.2–13 ms |
| Laya0.421B | 1 card | $1,500 | 10–22 ms |
| Kev-4B4B | 1 card | $1,500 | 25–53 ms |
| lev4B | 1 card | $1,500 | 74–160 ms |
| OpenJev27B | 1 card | $1,500 | 89–191 ms |
| Clef27B | 1 card | $1,500 | 89–191 ms |
| Perplexity Decider v1.227B | 1 card | $1,500 | 89–191 ms |
| mammoth-127B | 1 card | $1,500 | 89–191 ms |
Decision models score the options you give them instead of writing text, so they're timed per question. The time is scaled from each model's reported speed on an RTX PRO 6000 by this card's compute and memory bandwidth, within about half either way. About the models.
Compare elsewhere
Search other shops for NVIDIA Quadro GV100. These open the shop's own search; we don't show their prices here.